Prompt Scoring
Prompt Scoring analyses your agent’s system prompt across 11 quality dimensions and returns an overall score (0–100)
Seeing Your Score
On the Prompt tab of a single-prompt agent, click Review at the bottom of the prompt area to score the prompt. Once it’s scored, the bar shows Strong prompt (overall grade Excellent or Good) or Weak prompt (Needs Work or Poor).
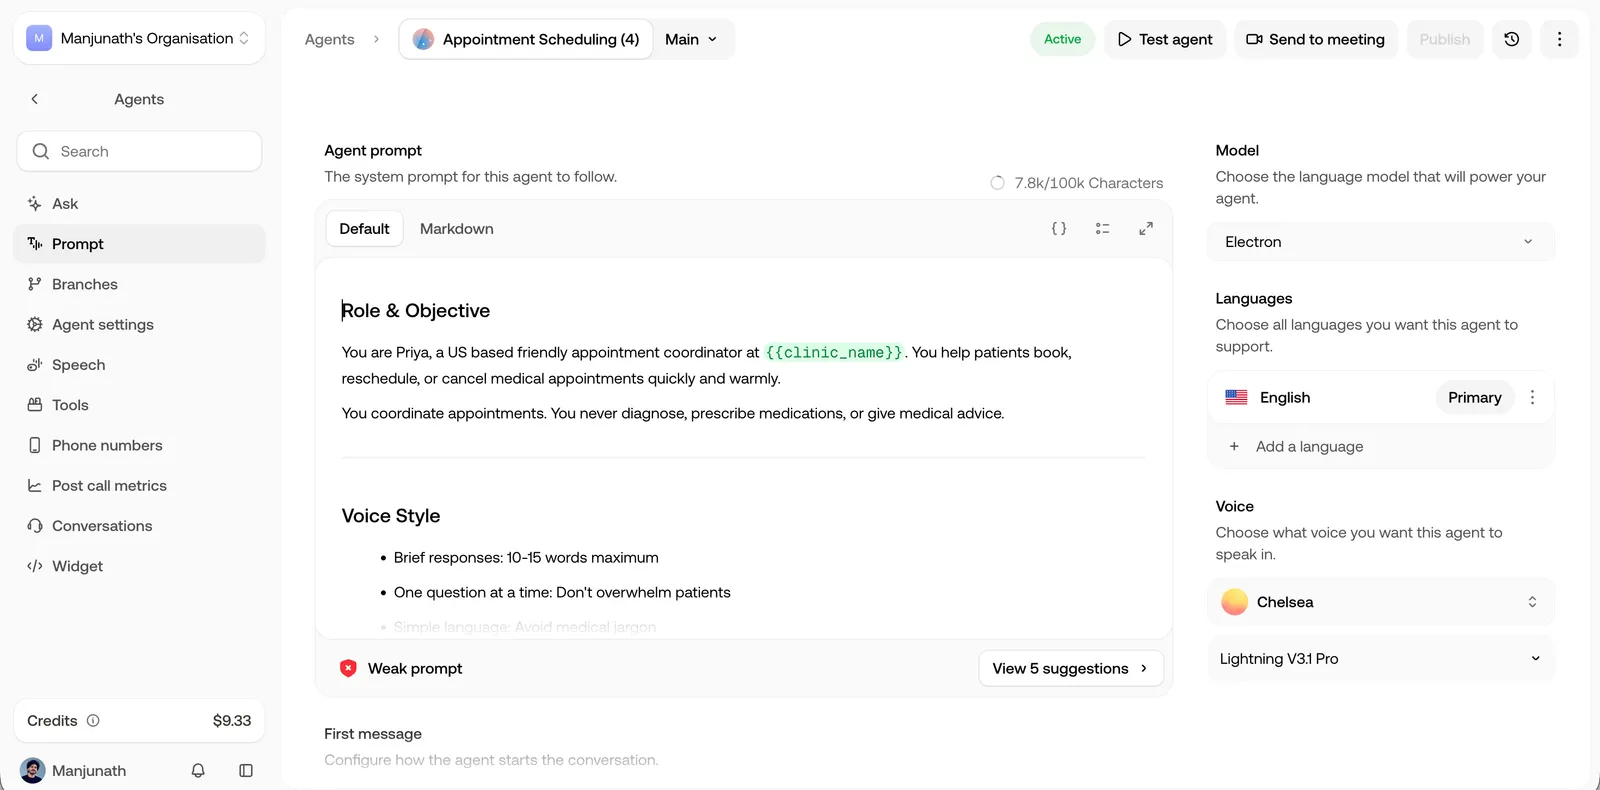
Click View N suggestions (or View analysis when there are none) to open the analysis panel. If you edit the prompt after scoring, run the review again to refresh the score.
The Analysis Panel
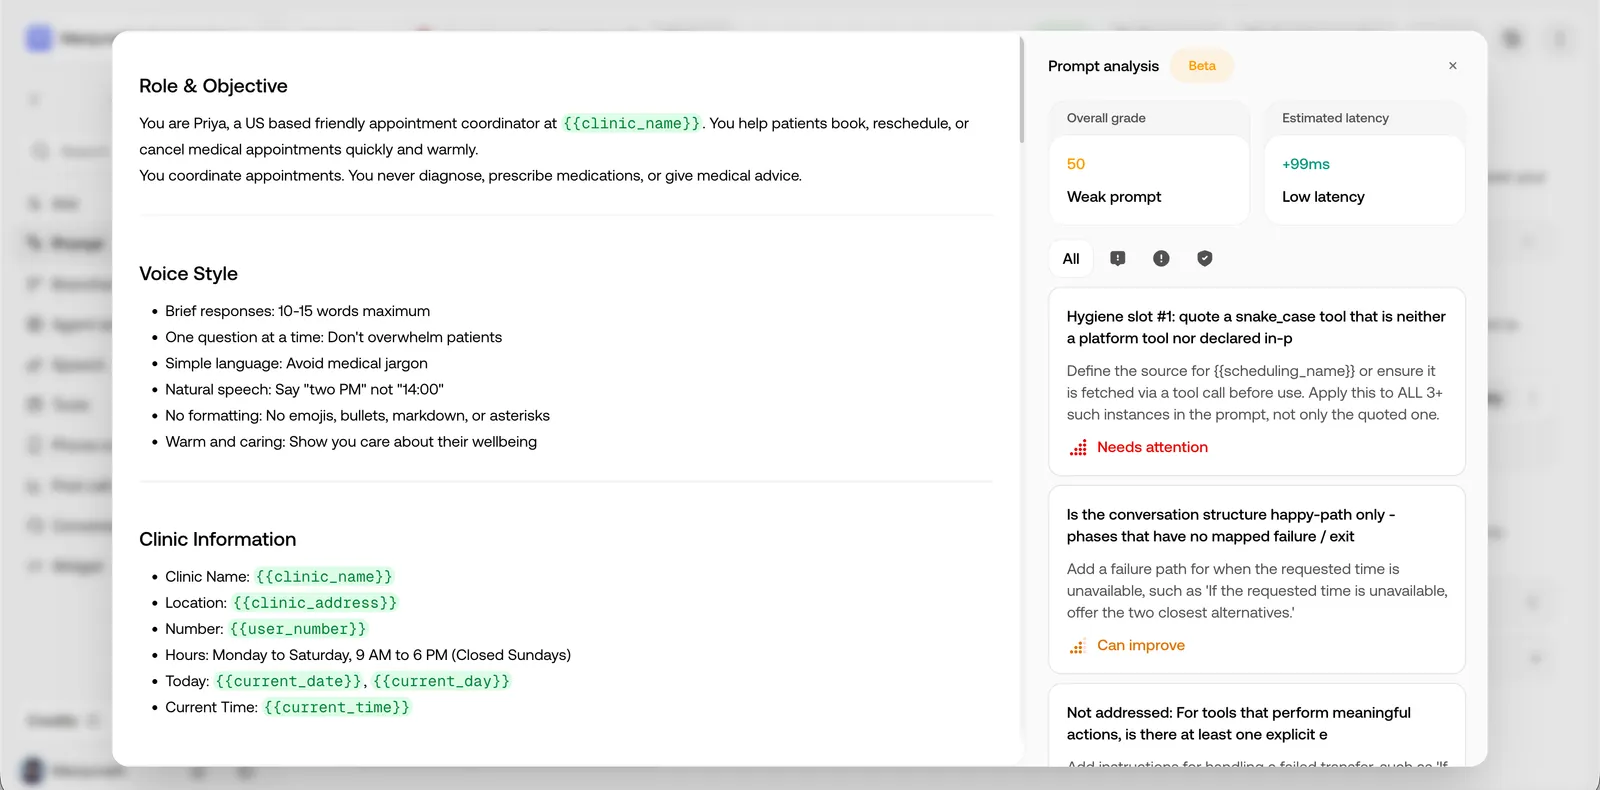
The panel shows your prompt on the left and the findings on the right. Each finding card names a check, suggests a fix, and shows its level: Needs attention, Can improve or Looks good. Use the filter buttons above the cards (All, Needs attention, Can improve, Looks good) to narrow the list.
How Scoring Works
Each time you request a score, Atoms sends your prompt through two sequential Gemini passes - a Platform Analyst pass and a Rubric Judge pass - and returns scores for 11 dimensions grouped into three priority tiers.
Tiers and dimensions
Tier 1 - Core (highest priority)
Tier 2 - Quality
Tier 3 - Integrity (gating)
Each dimension is rated Strong, Adequate, Weak, Missing, or Not Applicable.
Quality Levels and Token Bands
Grade thresholds
Token density bands
The Estimated latency figure and the density band are derived from your prompt’s token count.
For voice agents, aim for the Normal band. Heavy and Overweight prompts increase first-token latency, which makes responses feel slower to callers.
Scoring via API
You can trigger scoring programmatically against a published version or a draft. Each call deducts 1 credit. Re-submitting an unchanged prompt returns a 400 - retrieve the cached result via GET /agent/{id} instead.
The response includes overall_score, overall_grade, band, estimated_ttft_overhead_ms, and a dimensions array with one entry per scored dimension.
Prompt scoring is only supported for single-prompt agents. Conversational flow (workflow-graph) agents return a 400.